Showing posts with label DNA. Show all posts

Tuesday, November 21, 2006

What is DNA ?

1. Nucleotides are the building stones of DNA.

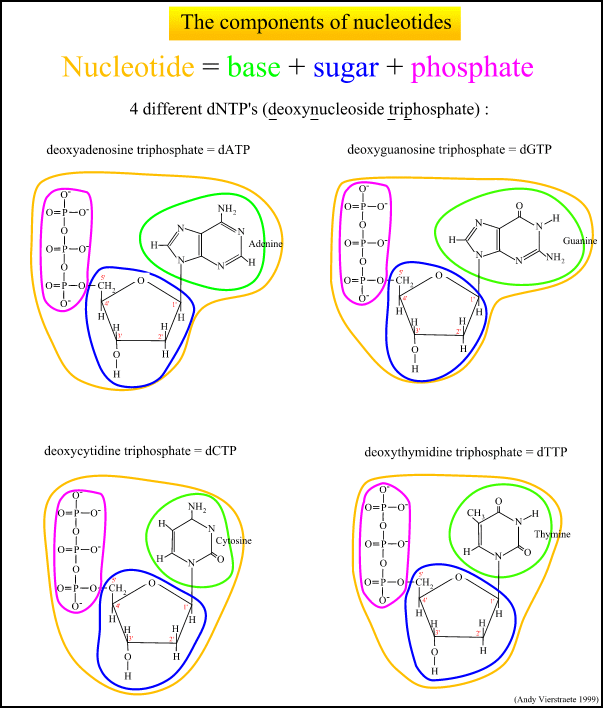
    There are 4 different nucleotides :
    • dATP : deoxyadenosine triphosphate
    • dGTP : deoxyguanosine triphosphate
    • dTTP : deoxythymidine triphosphate
    • dCTP : deoxycytidine triphosphate
    For convenience, these 4 nucleotides are called dNTP's (deoxynucleoside triphosphates). A nucleotide is made of three major parts : a nitrogen base, a sugar molecule and a triphosphate. Only the nitrogen base is different in the 4 nucleotides.


    Figure: The components of nucleotides. (pdf file of this picture)

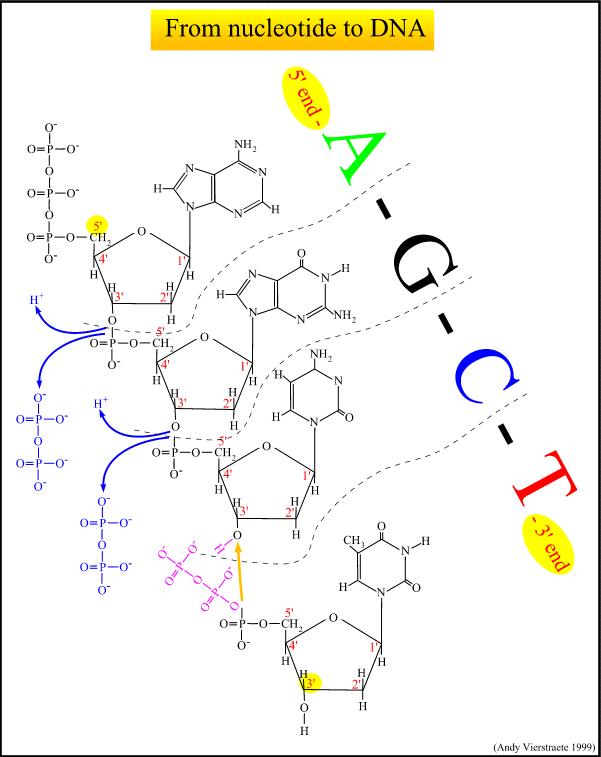
2. How do the nucleotides form a DNA chain ?


    Figure: From nucleotide to DNA. (pdf file of this picture) DNA is formed by coupling the nucleotides between the phosphate group from a nucleotide (which is positioned on the 5th C-atom of the sugar molecule) with the hydroxyl on the 3rd C-atom on the sugar molecule of the previous nucleotide. To accomplish this, a diphosphate molecule is split off (and releases energy). This means that new nucleotides are always added on the 3' side of the chain.

What is DNA Sequence Alignment?

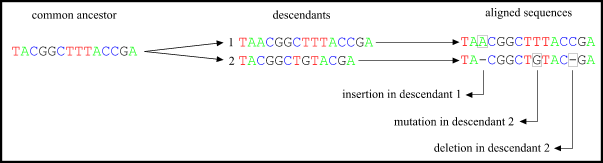
To compare two or more sequences, it is necessary to align the conserved and unconserved residues across all the sequences (identification of locations of insertions and deletions that have occurred since the divergence of a common ancestor). These residues form a pattern from which the relationship between sequences can be determined with phylogenetic programs. When the sequences are aligned, it is possible to identify locations of insertions or deletions since their divergence from their common ancestor. There are three possibilities :

  • The bases match : this means that there is no change since their divergence.
  • The bases mismatch : this means that there is a substitution since their divergence.
  • There is a base in one sequence, no base in the other : there is an insertion or a deletion since their divergence.
Figure: The comparison of sequences. A good alignment is important for the next step : the construction of phylogenetic trees. The alignment will affect the distances between 2 different species and this will influence the inferred phylogeny. There are several programs available on the net for aligning sequences. These are all based on different mathematical models to compare two or more sequences with the most optimal score for matching bases with a minimum number of gaps inserted (because you can insert a huge amount of gaps, so every base will match an other).
Example : two sequences :
TCAGACGATTG
TCGGAGCTG

How can we get the best alignment ? There are several possibilities : 1. Reduce the number of mismatches :
TCAG-ACG-ATTG
|| | | | | | 0 mismatches 7 matches 6 gaps
TC-GGA-GC-T-G
2. Reduce the number of gaps :
TCAGACGATTG
|| || 5 mismatches 4 matches 2 gaps
TCGGAGCTG--
3. Reduce neither the number of gaps nor the number of mismatches :
TCAG-ACGATTG
|| | | | | 2 mismatches 6 matches 4 gaps
TC-GGA-GCTG-
4. Same as 3. but one base (or gap) moved :
TCAG-ACGATTG
|| | | | | | 1 mismatch 7 matches 4 gaps
TC-GGA-GCT-G
Which of these is now the best alignment ?? There are several alignment algorithms to choose the best alignment. Let's use a simple one in this example :

D = y + sum(wkzk)

with :

D = distance
y : number of mismatches
w : penalty for gaps of length k
z : number of gaps of length k

Take gap penalty for gap length 1 = 2
Take gap penalty for gap length 2 = 6 (short gaps occur more frequent than long gaps)

in 1. : 0 + {(2 x 6) + (6 x 0)} = 12
in 2. : 5 + {(2 x 0) + (6 x 1)} = 11
in 3. : 2 + {(2 x 4) + (6 x 0)} = 10
in 4. : 1 + {(2 x 4) + (6 x 0)} = 9

We choose alignment 4 because it has the minimum distance.
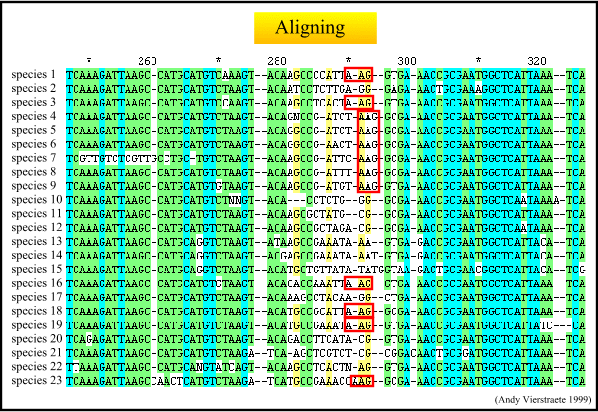
Figure: The alignment of sequences. This is done with Clustalw 1.74, and as you can see, the more variable areas are not optimally aligned (indicated with red boxes). Therefore it is mostly necessary to improve the alignment by hand. In this case, it is obvious to improve the alignment, but in other cases it could be more difficult to make improvements.
The Principle of DNA Sequencing

The purpose of sequencing is to determine the order of the nucleotides of a gene. For sequencing, we don't start from gDNA (like in PCR) but mostly from PCR fragments or cloned genes.

  1. The sequencing reaction :
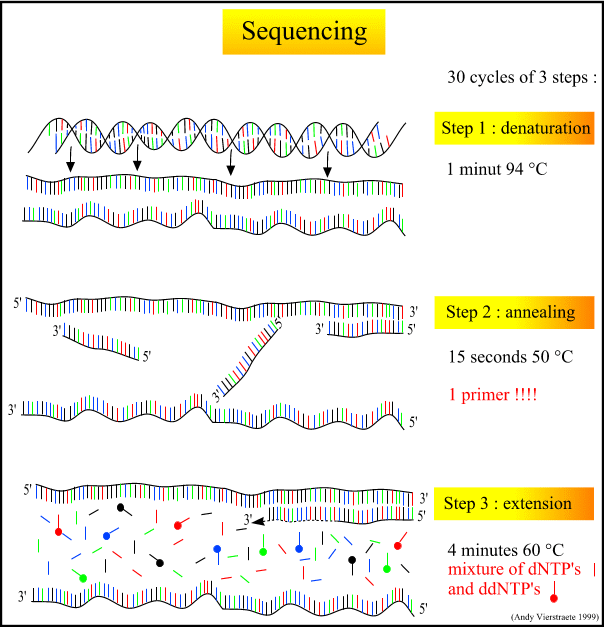
  2. There are three major steps in a sequencing reaction (like in PCR), which are repeated for 30 or 40 cycles.

    1. Denaturation at 94°C :

    2. During the denaturation, the double strand melts open to single stranded DNA, all enzymatic reactions stop (for example : the extension from a previous cycle).

    3. Annealing at 50°C :

    4. In sequencing reactions, only one primer is used, so there is only one strand copied (in PCR : two primers are used, so two strands are copied). The primer is jiggling around, caused by the Brownian motion. Ionic bonds are constantly formed and broken between the single stranded primer and the single stranded template. The more stable bonds last a little bit longer (primers that fit exactly) and on that little piece of double stranded DNA (template and primer), the polymerase can attach and starts copying the template. Once there are a few bases built in, the ionic bond is so strong between the template and the primer, that it does not break anymore.

    5. extension at 60°C :

    6. This is the ideal working temperature for the polymerase (normally it is 72 °C, but because it has to incorporate ddNTP's which are chemically modified with a fluorescent label, the temperature is lowered so it has time to incorporate the 'strange' molecules. The primers, where there are a few bases built in, already have a stronger ionic attraction to the template than the forces breaking these attractions. Primers that are on positions with no exact match, come loose again and don't give an extension of the fragment.

      The bases (complementary to the template) are coupled to the primer on the 3'side (adding dNTP's or ddNTP's from 5' to 3', reading from the template from 3' to 5' side, bases are added complementary to the template).

      When a ddNTP is incorporated, the extension reaction stops because a ddNTP contains a H-atom on the 3rd carbon atom (dNTP's contain a OH-atom on that position). Since the ddNTP's are fluorescently labeled, it is possible to detect the color of the last base of this fragment on an automated sequencer.

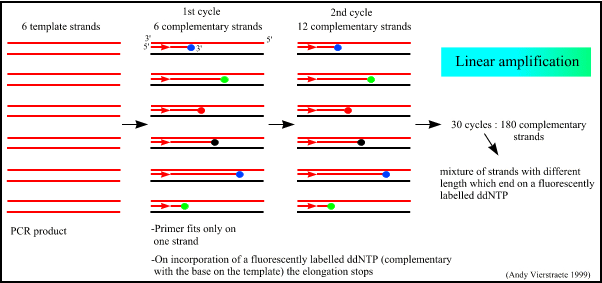
    Figure 7 : The different steps in sequencing. (pdf file of this picture)Animated picture of sequencing (344 kB) Because only one primer is used, only one strand is copied during sequencing, there is a linear increase of the number of copies of one strand of the gene. Therefore, there has to be a large amount of copies of the gene in the starting mixture for sequencing. Suppose there are 1000 copies of the wanted gene before the cycling starts, after one cycle, there will be 2000 copies : the 1000 original templates and 1000 complementary strands with each one fluorescent label on the last base, after two cycles, there will be 2000 complementary strands, three cycles will result in 3000 complementary strands and so on.


    Figure 8 : The linear amplification of the gene in sequencing.

  1. Separation of the molecules :
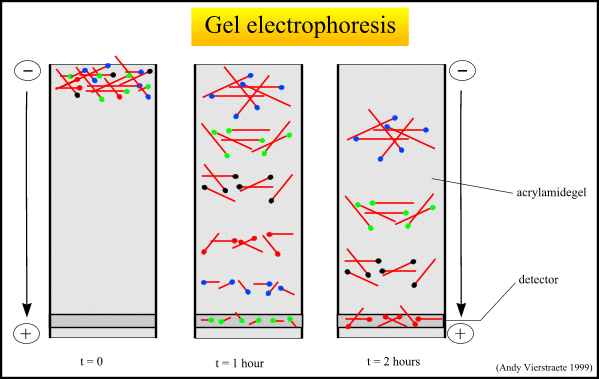
  2. After the sequencing reactions, the mixture of strands, all of different length and all ending on a fluorescently labelled ddNTP have to be separated; This is done on an acrylamide gel, which is capable of separating a molecule of 30 bases from one of 31 bases, but also a molecule of 750 bases from one of 751 bases. All this is done with gel electrophoresis. DNA has a negative charge and migrates to the positive side. Smaller fragments migrate faster, so the DNA molecules are separated on their size.

    Figure 9 : The separation of the molecules with electrophoresis.(pdf file of this picture)Animated picture of gel electrophoresis (159 kB)

  1. Detection on an automated sequencer :
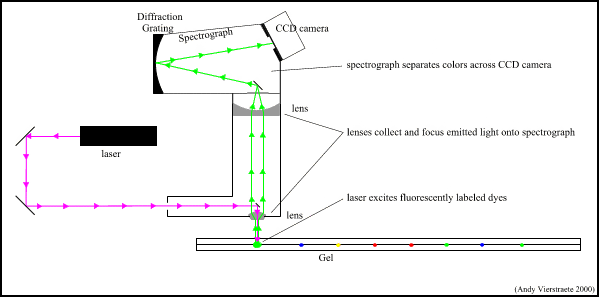
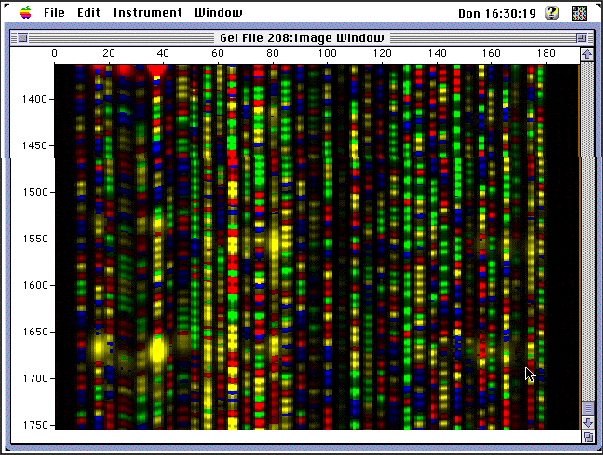
  2. The fluorescently labelled fragments that migrate trough the gel, are passing a laser beam at the bottom of the gel. The laser exites the fluorescent molecule, which sends out light of a distinct color. That light is collected and focused by lenses into a spectrograph. Based on the wavelength, the spectrograph separates the light across a CCD camera (charge coupled device). Each base has its own color, so the sequencer can detect the order of the bases in the sequenced gene.
    Figure 10 : The scanning and detection system on the ABI Prism 377 sequencer. (pdf file of this picture)Animated picture of scanning and detection system (182 kB)

Figure 11 : A snapshot of the detection of the molecules on the sequencer.


  1. Assembling of the sequenced parts of a gene :
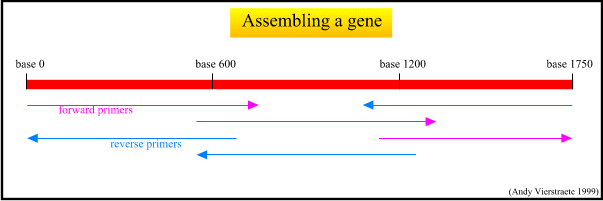
  2. For publication purposes, each sequence of a gene has to be confirmed in both directions. To accomplish this, the gene has to be sequenced with forward and reverse primers. Since it is only possible to sequence a part of 750 till 800 bases in one run, a gene of, for example 1800 bases, has to be sequenced with internal primers. When all these fragments are sequenced, a computer program tries to fit the different parts together and assembles the total gene sequence.

    Figure 12 : The assemblage of the gene.
More information in power point and pdf format.